A cage waiting for a no
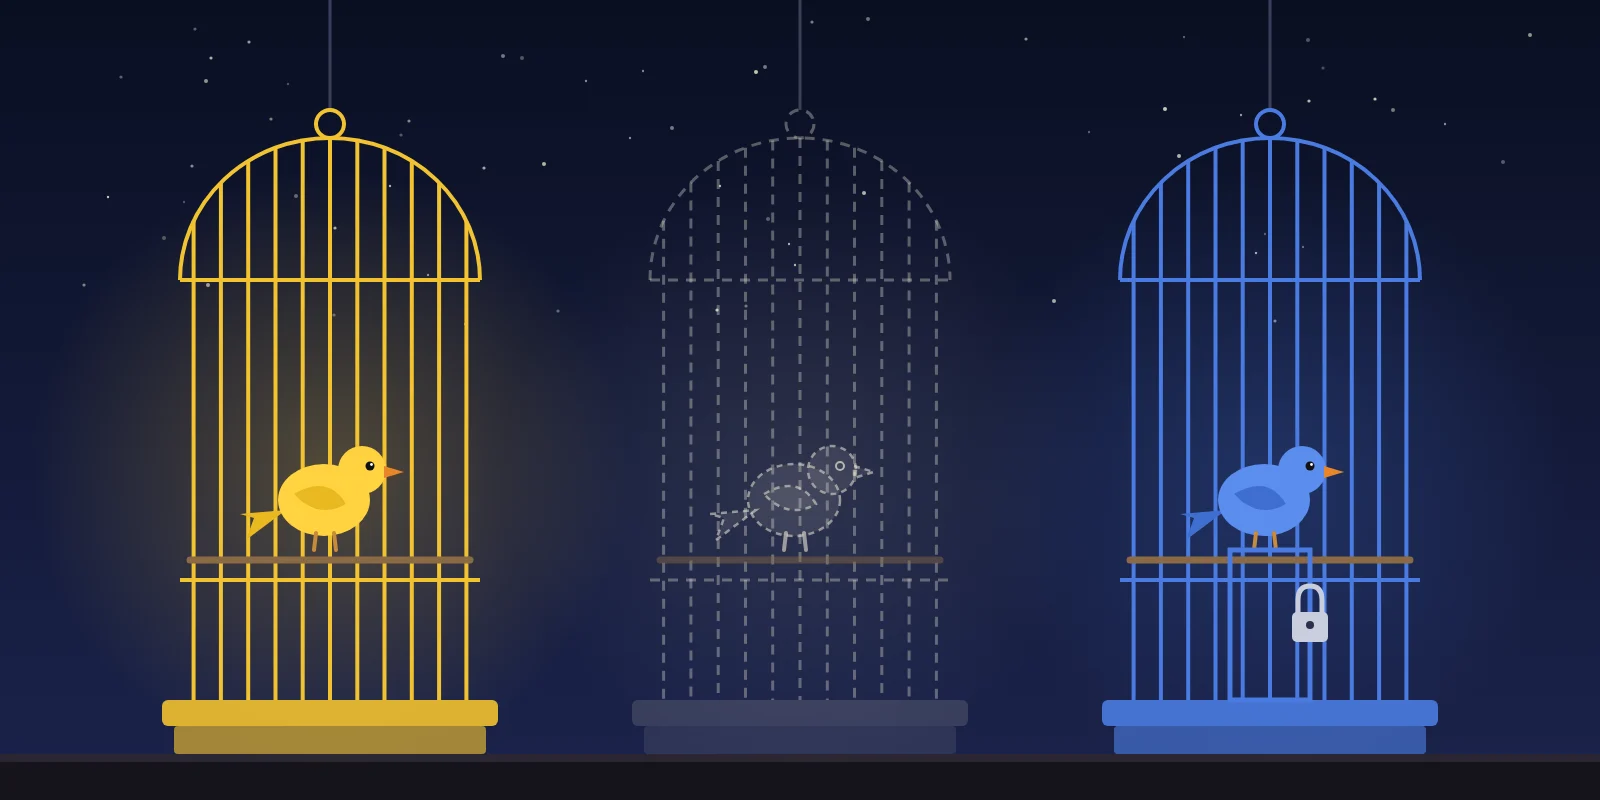
The yellow and the see-through cage are open: their words may be used to train AI models. The blue cage is meant to test the opposite. Here stands an explicit no to training, and the question is whether the providers respect it.
Planned signal in robots.txt: User-Agent: __usage_ai-training, Disallow
Opens as soon as OpenAI demonstrably honours the signal
Part of an experiment with several cages.
What is happening right now
For a long time there was no shared no. Every company had its own switch in robots.txt: Google calls it Google-Extended, Apple Applebot-Extended, OpenAI GPTBot, Anthropic ClaudeBot. Anyone who wanted to keep their work out of training had to lock out each company one by one.
Since 2025 a working group at the IETF has been building a common language for such wishes. The IETF is the body that sets the technical rules of the internet. Its drafts are not finished yet.
On 30 October 2026 things started to move. Anthropic, Google, Microsoft and OpenAI announced they will honour one shared signal: a line of its own in robots.txt that says only one thing. Please do not use these pages to train AI models. It does not forbid reading the page. It is a wish about how what was read gets used.
It is arriving step by step. Anthropic says it has already started. OpenAI plans to follow in the coming months, Microsoft from February 2027, Google during 2027. Apple, Meta and Perplexity have not committed so far.
Two limits remain. The signal is voluntary, nobody can enforce it technically. And it only works going forward: what has already been collected stays collected.
Europe is already further along
In the EU a no to training is more than a polite request. Rights holders may forbid the automated analysis of their works for commercial purposes. In Germany this has been in copyright law since 2021. The condition: the reservation has to be machine readable.
Since August 2025 the EU AI Act has required providers of large AI models to respect such reservations. Since August 2026 the EU AI Office can enforce this with fines. Most large providers have signed a voluntary code of practice that names robots.txt explicitly. Meta has not signed it.
A case from Hamburg shows how closely courts look. A photographer did not want his pictures used for training. But the reservation was written only in plain language, in the terms of use. At the end of 2025 the Higher Regional Court of Hamburg ruled: that is not enough, a reservation has to be readable by machines.
That training leaves traces was confirmed by the Regional Court of Munich in November 2025. ChatGPT could reproduce song lyrics it had learned in training. GEMA, the German music rights society, had sued, and the court found a copyright infringement. This experiment looks for exactly such traces, only with invented words instead of lyrics.
Why the cage is still closed
The commitments are there, the implementation is not yet. A fair test needs a provider that actually honours the no. Otherwise a hit only shows that it learned something it was still allowed to learn at that time.
So this cage stays empty until OpenAI demonstrably honours the signal. Then the words go in, and from that day the clock runs. For every other provider, the day it implements the signal is the day that counts.